On a cluster configured with a CPU model such as cpu-model.node.kubevirt.io/Cascadelake-Server=true, virtual machines may no longer start after an upgrade to Harvester v1.7.3.
The mitigation for CVE-2019-11135 disables TSX on affected CPUs. As a result, the hle and rtm CPU features are missing on those nodes, and virtual machines that require them cannot start.
If the output reports Vulnerable, use the corresponding CPU model ending in -noTSX (for example, Skylake-Server-noTSX or Cascadelake-Server-noTSX) to disable TSX for the virtual machine. Interpret other output according to your operating system's security guidance. Make sure the selected model is supported by every node where the virtual machine may run.
Alternatively, configure Cascadelake-Server-v3 or a later version as the CPU model. After changing the CPU model, restart all affected virtual machines.
This article explains how to install the NetApp Trident CSI driver on a Harvester cluster. Once it's installed, VMs running in Harvester can store their volumes on a NetApp ONTAP storage system.
NetApp storage is added alongside Longhorn; it does not replace it. You can use any combination of these protocols:
NFS (ontap-nas)
iSCSI (ontap-san, sanType: iscsi)
NVMe/TCP (ontap-san, sanType: nvme)
Fibre Channel (ontap-san, sanType: fcp)
This procedure was tested with Harvester v1.9.0 and Trident 26.06.1 (Helm chart 100.2606.1), using ONTAP 9.16.1. With NFS, iSCSI and NVMe/TCP, the following worked on NetApp-backed volumes: booting VMs, live migration, online volume expansion, and Harvester VM snapshots. Trident also supports Fibre Channel, and the multipath configuration below covers FC LUNs. However, FC was not tested for this article.
note
This article replaces an earlier version (August 2023) written for Harvester v1.2.0 and Trident v23.07. The main changes:
Multipath is now configured with a Harvester CloudInit resource, instead of files edited by hand on every node.
Backends are now TridentBackendConfig resources, so tridentctl is no longer needed.
NFS and NVMe/TCP are now covered.
The extra ClusterRole for PSA (NetApp/trident#839) was not needed in testing.
Third-party volumes can now be used as VM boot volumes.
A Harvester cluster and its KubeConfig. To download it, open the Harvester UI, click Support in the lower left, then click Download KubeConfig.
A workstation with kubectl and helm that can reach the Harvester cluster.
An ONTAP SVM with:
A management LIF that the Harvester nodes can reach.
Data LIFs for each protocol you plan to use: NFS, iSCSI, NVMe/TCP and/or FC. NVMe/TCP requires the NVMe_oF license on the ONTAP system.
An ONTAP login for Trident with the http and ontapi applications enabled, using the SVM-scoped vsadmin role. Point managementLIF at the SVM's own management LIF; Trident then infers the SVM from that connection, so the backends below don't need an explicit svm field either. See User permissions in the Trident documentation.
For FC only: FC HBAs in every Harvester node that mounts NetApp volumes, and fabric zoning between those HBAs and the SVM's FC LIFs.
Trident's node plugin runs in the host network namespace, so the host's routing table decides which NIC carries storage traffic.
tip
Avoid sending storage traffic over the management network. It's shared with the cluster control plane and the pod network, and adds overhead. For production, use a dedicated cluster network on its own NICs, as described in the next section.
How Trident discovers data LIFs differs by protocol:
iSCSI / NVMe/TCP: Trident ignores dataLIF on SAN backends and logs Specifying data LIF is no longer supported for SAN backends. It asks ONTAP for every SAN LIF in the SVM, and each node logs in to all of them, so multipath works automatically. You only need managementLIF.
NFS: dataLIF takes a single address. If you leave it out, Trident uses the first NFS LIF it finds in the SVM. Set it explicitly to choose the network that carries NFS traffic.
FC: traffic runs over the FC fabric, not the IP network, so the rest of this section does not apply. Only the management LIF must be reachable over IP.
Optional: a dedicated storage interface with HostNetworkConfig
This takes two steps: create a cluster network on the storage NICs, then give each host an IP address on it with a HostNetworkConfig.
Step 1: create the cluster network. A cluster network groups the storage NICs into a bridge on each node. See Create a New Cluster Network for details.
In the Harvester UI, go to Networks > ClusterNetworks/Configs and click Create. Name it, for example cn-storage.
Click Create Network Config on the new cluster network.
On the Node Selector tab, select the nodes that mount NetApp volumes. Select all nodes does not work if the cluster has a witness node. Select nodes by name, or by a label such as netapp-trident=enabled (see the note further down).
On the Uplink tab, select the storage NICs, the bond mode, and the MTU. The MTU must match the switch ports and the ONTAP LIFs, for example 9000 for jumbo frames.
Click Save.
The switch ports for these NICs must be trunk ports that carry the storage VLAN tagged.
Step 2: give the hosts an IP address on it. On its own, a cluster network carries only VM traffic, because the hosts have no IP address on it. A HostNetworkConfig (Networks > Host Networks) creates a VLAN sub-interface on the cluster network's bridge on each node and gives it an IP address. Traffic to the ONTAP data LIFs on that subnet then leaves through that interface instead of the management network. The ONTAP data LIFs must be on the same VLAN and subnet.
Check the result on a node with ip addr show cn-storage-br.150. Each node's state is reported in the resource's status.nodeStatus.
Static mode and witness nodes
In static mode without a nodeSelector, the webhook requires an IP for every node in the cluster, witness included. Otherwise it rejects the resource with static IP not found for node <witness>. You have two options:
Add a nodeSelector, as in the example above. Only the matching nodes then need an entry in ips. The selector can use the same netapp-trident=enabled label that restricts the Trident node plugin. This way the witness is excluded from the storage network and from Trident consistently.
Give the witness an IP as well. It costs one address on the storage subnet. The witness never mounts volumes, so the address goes unused.
In static mode, new nodes are not configured automatically. Add their entry to ips (and the label, if you use one) when they join.
For iSCSI, you can add a second cluster network (or a second VLAN) with its own HostNetworkConfig and LIFs, so multipath has two independent paths.
iSCSI and FC LUNs need multipathd, which is not enabled on Harvester by default. Both protocols present NetApp LUNs with vendor NETAPP and product LUN, so the same configuration covers them. The configuration below lets multipathd claim only NetApp LUNs. Every other device is blacklisted, so Longhorn and the local disks are never touched. Harvester's own /etc/multipath/conf.d/99-longhorn.conf is left as is.
caution
Never start multipathd before the NetApp-only configuration is in place. With its default configuration, multipathd claims local disks, including Longhorn disks, as dm multipath devices.
The following CloudInit resource writes /etc/multipath/conf.d/98-netapp.conf and enables multipathd on every node. It is re-applied on every boot. Save it as 01-cloudinit-netapp-multipathd.yaml:
Despite the initramfs stage name, Harvester's node CloudInit controller writes the file and runs the network stage as soon as the resource is created — no reboot needed. Confirm the file actually merged into the running daemon's config (don't rely on multipath -ll alone, since it's empty if no LUN happens to be attached yet):
multipathd -k"show config"|grep -A6 '^blacklist {'# must show vendor ".*" / product ".*"
If you'd rather apply it by hand instead of waiting on the controller, run the following on each node as root. It writes the same file and starts multipathd, and stops at the first failure:
set -e mkdir -p /etc/multipath/conf.d cat> /etc/multipath/conf.d/98-netapp.conf <<'EOF' defaults { user_friendly_names yes find_multipaths no reservation_key file skip_kpartx yes } blacklist { device { vendor ".*" product ".*" } } blacklist_exceptions { device { vendor "NETAPP" product "LUN.*" } } EOF systemctl enable --now multipathd multipath -ll # must not list any local disk
note
NVMe/TCP does not use dm-multipath. It uses native NVMe multipath, which is already enabled in the Harvester kernel, and doesn't need nvme-cli on the host.
NFS needs no host configuration.
Check that every node has a unique iSCSI initiator name. Nodes cloned from the same image can end up with the same name in /etc/iscsi/initiatorname.iscsi. ONTAP then treats those nodes as a single host. If you change a node's IQN, restart that node's trident-node-linux pod afterwards. Trident caches the IQN, and with a stale one volume staging fails with no devices present yet.
Pick a version from the helm search output above rather than pinning one in this article; this procedure was tested with chart 100.2606.1 (Trident 26.06.1).
Wait until the trident-controller pod and one trident-node-linux pod per node are Running:
kubectl -n trident get pods -o wide
Optional: run the node plugin only on selected nodes
By default, the trident-node-linux DaemonSet tolerates all NoSchedule and NoExecute taints, so it runs on every node, including a witness node. A witness node only runs etcd and never mounts volumes, so you may want to keep Trident off it. The same approach works for keeping Trident on any subset of nodes that host NetApp-backed VMs.
Label the nodes that should mount NetApp volumes, then pass the label to the chart:
When you add a node to the cluster later, label it too. Otherwise VMs scheduled on it cannot mount NetApp volumes.
If you use a dedicated storage interface, use the same label as the HostNetworkConfig nodeSelector. Then the nodes that run Trident and the nodes with an IP on the storage network are always the same set.
VMs using NetApp volumes must only run on the labelled nodes. A Harvester witness node never runs VMs, so this needs no extra configuration in the witness case.
Create one TridentBackendConfig per protocol you use; you can drop any you don't need.
A few things the examples below deliberately leave out:
spaceReserve: none and snapshotReserve: "0": these are already Trident's defaults, so setting them changes nothing. (Don't confuse snapshotReserve with thin provisioning, either — it reserves extra space on the ONTAP volume so a PVC's filesystem doesn't run out of room as Snapshot copies grow, it isn't what makes the volume thin.)
limitAggregateUsage: this stops Trident from creating new volumes once an aggregate passes a given percent used, but aggregates are cluster-level ONTAP objects, so it only works with a cluster-scopedadmin login — strictly more access than Trident needs for anything else in this article. On all-flash aggregates there's also no performance cliff near 80% full the way there was with spinning disks, so there's less reason to want it. Watch aggregate usage with your normal ONTAP monitoring instead.
svm and dataLIF: not needed if managementLIF already points at an SVM-scoped management LIF (Trident infers the SVM from that LIF) and the SVM has only one data LIF per protocol, which is the recommended design. If your SVM has several LIFs for the same protocol, set dataLIF on the NFS backend to pick one explicitly (see Network design).
nfsMountOptions: this is a Trident-side fallback, not the Kubernetes-native way to set mount options — it doesn't show up in the resulting PV's mountOptions field. Set mount options on the StorageClass instead (step 5).
If several Kubernetes or Harvester clusters share one SVM, give each cluster a unique backendName and set storagePrefix (for example storagePrefix: hv1_). That keeps volume names from colliding and makes each cluster's volumes easy to identify in ONTAP.
For Fibre Channel, copy the iSCSI backend below, then change name and backendName (for example to netapp-fc) and set sanType: fcp. Then add a matching StorageClass in step 5 with sanType: fcp. FC was not tested for this article.
Save as 03-backends.yaml, replacing the <...> values:
kubectl apply -f 03-backends.yaml
kubectl -n trident get tridentbackendconfigs
Every backend must report PHASEBound and STATUSSuccess. If one doesn't, kubectl -n trident describe tridentbackendconfig <name> shows the error.
5. Create the StorageClasses and VolumeSnapshotClass
A StorageClass with only backendType: ontap-san can place a volume on any SAN backend: iSCSI, NVMe/TCP or FC. Pin each class to a protocol with the sanType parameter (iscsi, nvme or fcp) instead of matching backends by name with storagePools — it's the more direct mechanism and keeps working if you ever rename a backend. storagePools is still the right tool if you run multiple SVMs and need to steer volumes to one of them.
For the NFS class, add fsType: "nfs". It's not needed to mount the volume, but without it Kubernetes skips applying a pod's fsGroup to the volume (no setgid bit, no group ownership change) — worth the one extra line. Mount options for NFS also belong here, as the StorageClass's top-level mountOptions, not on the backend.
Live migration requires ReadWriteMany volumes. CDI already knows Trident's defaults:
ontap-san (iSCSI, NVMe/TCP and FC): ReadWriteMany with volumeMode: Block.
ontap-nas: ReadWriteMany with volumeMode: Filesystem.
So these StorageClasses don't need the cdi.harvesterhci.io/storageProfileVolumeModeAccessModes annotation. None of the other cdi.harvesterhci.io/storageProfile* annotations from older third-party storage write-ups are needed either — check kubectl get storageprofile <storageclass> -o yaml after creating the class, and its status is already filled in (access modes, cloneStrategy: snapshot, snapshotClass) because CDI recognizes csi.trident.netapp.io directly. The separate storageclass.kubevirt.io/is-default-virt-class annotation is unrelated to any of this — it only matters if you want a NetApp class, instead of Longhorn, to be the default for new VM disks.
Harvester needs to know which VolumeSnapshotClass to use for Trident volumes.
In the Harvester UI, go to Advanced > Settings, find csi-driver-config, and select ⋮ > Edit Setting.
Click Add, then fill in the fields:
Provisioner: csi.trident.netapp.io
Volume Snapshot Class Name: trident-snapshotclass
Save.
Leave Backup Volume Snapshot Class Name empty. In Harvester v1.9, VM backups only work with Longhorn volumes. VM snapshots of Trident volumes work. See Third-Party Storage Support.
The resulting entry in the setting's JSON value is:
Backends go offline after the ONTAP system was unreachable. If they don't recover on their own, restart the controller: kubectl -n trident rollout restart deploy/trident-controller.
Deleted volumes still use space on ONTAP. ONTAP keeps deleted volumes in the volume recovery queue for 12 hours. While a deleted FlexClone (such as a VM disk cloned from an image) sits in the queue, its parent snapshot stays busy, so the parent volume and its VolumeSnapshot can't be deleted. To free them immediately, run on ONTAP: set -privilege advanced; volume recovery-queue purge-all -vserver <svm name>.
multipath -ll lists local disks.multipathd was started without the NetApp-only configuration. Put 98-netapp.conf in place, flush the unused maps with multipath -F, and restart multipathd.
iSCSI volumes fail to stage with no devices present yet. Check for duplicate initiator names across nodes, and for a stale IQN in Trident (see step 1).
Harvester v1.7.0 introduced the kubevirt-migration setting, which exposes the cluster-wide live migration configuration that previously could only be changed by editing the kubevirt object directly.
If you customized spec.configuration.migrations on the kubevirt object before upgrading, that customization is at risk. This article explains why and provides a script that converts it into the setting so it is preserved.
You are affected if both of the following are true:
You are running a version earlier than v1.7.0 and you changed spec.configuration.migrations on the kubevirt object, for example to enable allowAutoConverge.
You plan to upgrade to v1.7.0 or later.
You are also affected if you have already upgraded to v1.7.x and have not yet changed the kubevirt-migration setting. In that case the configuration is still intact and the same script applies.
Check whether the kubevirt object carries a configuration:
kubectl get kubevirt kubevirt -n harvester-system -o jsonpath='{.spec.configuration.migrations}'| jq
If the command returns nothing, your cluster uses the KubeVirt defaults and no action is required.
The upgrade creates the kubevirt-migration setting without a value, so the Harvester UI displays the default values. The kubevirt object keeps your configuration, so live migration continues to behave as before.
The two are now inconsistent, and the inconsistency is not visible unless you compare them. Harvester writes the whole value of the setting to the kubevirt object, so the first time the setting is saved, all fields are written at once, including the fields that you did not change. Your configuration is replaced by the defaults, without warning.
In practice this means that changing an unrelated field such as parallelMigrationsPerCluster in the UI silently turns allowAutoConverge back off. Migrations of write-heavy virtual machines then start failing to converge, which is often noticed only during the node drains of a later upgrade.
Run the following script from a machine with kubectl access to the cluster. jq is required.
Run it before you upgrade to v1.7.0 or later. If you already upgraded to v1.7.x and have not yet changed the setting, run it now.
#!/bin/bash set -euo pipefail SETTING_NAME="kubevirt-migration" migrations=$(kubectl get kubevirt kubevirt -n harvester-system -o json | jq -c '.spec.configuration.migrations // empty') if[ -z "$migrations"];then echo"The kubevirt object has no migration configuration. Nothing to preserve." exit0 fi # nodeDrainTaintKey and network cannot be configured through the setting: # nodeDrainTaintKey is used by the upgrade process, and network is owned by # the vm-migration-network setting. The webhook rejects a value containing them. value=$(echo"$migrations"| jq -c 'del(.nodeDrainTaintKey, .network)') if["$value"="{}"];then echo"The migration configuration only contains fields that the setting does not manage. Nothing to preserve." exit0 fi ifsetting_json=$(kubectl get settings.harvesterhci.io "$SETTING_NAME" -o json 2>/dev/null);then current_value=$(echo"$setting_json"| jq -r '.value // empty') if[ -n "$current_value"];then echo"The $SETTING_NAME setting already has a value. Nothing to do." exit0 fi echo"Setting $SETTING_NAME to: $value" kubectl patch settings.harvesterhci.io "$SETTING_NAME" --type merge \ -p "$(jq -n --arg v"$value"'{"value": $v}')" else echo"Creating $SETTING_NAME with: $value" kubectl apply -f - <<EOF apiVersion: harvesterhci.io/v1beta1 kind: Setting metadata: name: $SETTING_NAME value: '$value' EOF fi echo"Result:" kubectl get settings.harvesterhci.io "$SETTING_NAME" -o yaml
The script does not write to the kubevirt object, so it cannot change how the cluster performs live migrations. It is idempotent: it does nothing if there is no configuration to preserve, or if the setting already has a value.
note
The Harvester webhook rejects changes to the kubevirt-migration setting while a virtual machine migration is in progress. If the script fails for that reason, wait until all migrations are completed and run it again.
The kubevirt-migration setting is the source of truth. Harvester writes it to the kubevirt object whenever the setting changes.
Do not edit spec.configuration.migrations on the kubevirt object directly. Any change is overwritten the next time the setting is reconciled. Use the setting instead, either in the Harvester UI under Advanced > Settings, or with kubectl.
For the list of supported fields and their defaults, see kubevirt-migration in the Harvester documentation.
When running production workloads on virtualized infrastructure like Harvester, memory management is critical. In Harvester versions prior to v1.4.0, certain workloads experienced sudden Virtual Machine (VM) terminations due to the host Linux operating system triggering Out-Of-Memory (OOM) kills.
What is KubeVirt? Harvester uses KubeVirt as its core virtualization engine. KubeVirt is an open-source technology that allows Kubernetes to run and manage traditional Virtual Machines inside standard containers, translating VM specifications directly into Pod configurations.
This article explores why these OOM events occur in a Kubernetes-native virtualization environment and how Harvester provides granular tools to eliminate them.
When a VM is terminated due to insufficient memory at the host level, the Linux kernel logs specific keywords that help pinpoint the fault. In Harvester, these logs generally fall into two distinct categories depending on which process triggered the exhaustion.
Example 1: virt-launcher invoked oom-killer
The virt-launcher process runs inside the dedicated Kubernetes Pod backing the VM. If this component or its direct sub-processes run out of the memory allocated to their cgroup, the kernel triggers a memory cgroup (memcg) OOM event.
Feb 03 19:57:08 ** kernel: virt-launcher invoked oom-killer: gfp_mask=0xcc0(GFP_KERNEL), order=0, oom_score_adj=986
Feb 03 19:57:08 ** kernel: CPU: 40 PID: 40785 Comm: virt-launcher Tainted: G          I    X    5.14.21-150400.24.60-default #1 SLE15-SP4 9096397fa6646928cc6d185ba417f2af65b536f1
...

Feb 03 19:57:08 ** kernel: memory: usage 17024340kB, limit 17024340kB, failcnt 1243
Feb 03 19:57:08 ** kernel: memory+swap: usage 17024340kB, limit 9007199254740988kB, failcnt 0
Feb 03 19:57:08 ** kernel: kmem: usage 143556kB, limit 9007199254740988kB, failcnt 0
Feb 03 19:57:08 ** kernel: Memory cgroup stats for /kubepods.slice/kubepods-burstable.slice/kubepods-burstable-pod968a06fb_9ab9_4819_8caf_0392ddff3d9b.slice:
...
Feb 03 19:57:08 ** kernel: Tasks state (memory values in pages):
Feb 03 19:57:08 ** kernel: [  pid  ]   uid  tgid total_vm      rss pgtables_bytes swapents oom_score_adj name
Feb 03 19:57:08 ** kernel: [  38886]     0 38886      243        1    28672        0          -998 pause
Feb 03 19:57:08 ** kernel: [  38917]     0 38917   310400     6921   192512        0           986 virt-launcher-m
Feb 03 19:57:08 ** kernel: [  38934]     0 38934  1200940    25126   954368        0           986 virt-launcher
Feb 03 19:57:08 ** kernel: [  38951]     0 38951   386525     8247   466944        0           986 libvirtd
Feb 03 19:57:08 ** kernel: [  38952]     0 38952    33619     3940   290816        0           986 virtlogd
Feb 03 19:57:08 ** kernel: [  39079]   107 39079  4457263  4201766 34439168        0           986 qemu-system-x86
Feb 03 19:57:08 ** kernel: oom-kill:constraint=CONSTRAINT_MEMCG,nodemask=(null),cpuset=cri-containerd-0f32894de86edf3d3832702af794874ef8d400b4969acdea4976b12040756e0d.scope,mems_allowed=0-1,oom_memcg=/kubepods.slice/kubepods-burstable.slice/kubepods-burstable-pod968a06fb_9ab9_4819_8caf_0392ddff3d9b.slice,task_memcg=/kubepods.slice/kubepods-burstable.slice/kubepods-burstable-pod968a06fb_9ab9_4819_8caf_0392ddff3d9b.slice/cri-containerd-0f32894de86edf3d3832702af794874ef8d400b4969acdea4976b12040756e0d.scope,task=qemu-system-x86,pid=39079,uid=107
Example 2: CPU X/KVM invoked oom-killer
This occurs when a vCPU execution thread inside qemu-system-x86_64 attempts a memory operation that pushes the entire container beyond its Kubernetes memory limit.
[Thu May  9 14:52:38 2024] CPU 11/KVM invoked oom-killer: gfp_mask=0xcc0(GFP_KERNEL), order=0, oom_score_adj=830
[Thu May  9 14:52:38 2024] CPU: 60 PID: 70888 Comm: CPU 11/KVM Not tainted 5.3.18-150300.59.101-default #1 SLE15-SP3
...
[Thu May  9 14:52:38 2024] memory: usage 67579904kB, limit 67579904kB, failcnt 67391
[Thu May  9 14:52:38 2024] memory+swap: usage 0kB, limit 9007199254740988kB, failcnt 0
[Thu May  9 14:52:38 2024] kmem: usage 633636kB, limit 9007199254740988kB, failcnt 0
...
[Thu May  9 14:52:38 2024] Tasks state (memory values in pages):
[Thu May  9 14:52:38 2024] [  pid  ]   uid  tgid total_vm      rss pgtables_bytes swapents oom_score_adj name
[Thu May  9 14:52:38 2024] [  70675]     0 70675      243        1    28672        0          -998 pause
[Thu May  9 14:52:38 2024] [  70728]     0 70728   310400     5467   188416        0           830 virt-launcher-m
[Thu May  9 14:52:38 2024] [  70746]     0 70746  1242373    25104  1073152        0           830 virt-launcher
[Thu May  9 14:52:38 2024] [  70762]     0 70762   455279    14110   770048        0           830 libvirtd
[Thu May  9 14:52:38 2024] [  70763]     0 70763    37704     3916   339968        0           830 virtlogd
[Thu May  9 14:52:38 2024] [  70870]   107 70870 18302464 16718510 135278592        0           830 qemu-system-x86
[Thu May  9 14:52:38 2024] oom-kill:constraint=CONSTRAINT_MEMCG,nodemask=(null),cpuset=cri-containerd-100093783c22a3ae1a42e21dd887b7c26eef52d56ba44c7273ef54507b6efe7c.scope,mems_allowed=0-3,oom_memcg=/kubepods.slice/kubepods-burstable.slice/kubepods-burstable-podef91e487_dec5_4613_800b_eb23e1a1617d.slice,task_memcg=/kubepods.slice/kubepods-burstable.slice/kubepods-burstable-podef91e487_dec5_4613_800b_eb23e1a1617d.slice/cri-containerd-100093783c22a3ae1a42e21dd887b7c26eef52d56ba44c7273ef54507b6efe7c.scope,task=qemu-system-x86,pid=70870,uid=107
[Thu May  9 14:52:38 2024] Memory cgroup out of memory: Killed process 70870 (qemu-system-x86) total-vm:73209856kB, anon-rss:66852088kB, file-rss:21948kB, shmem-rss:4kB
[Thu May  9 14:52:38 2024] oom_reaper: reaped process 70870 (qemu-system-x86), now anon-rss:0kB, file-rss:132kB, shmem-rss:4kB
Root Cause: Native Hypervisors vs. Harvester Architecture
Traditional Linux Host (e.g., Virtual Machine Manager)
On a standard Linux host, a VM managed via QEMU/KVM runs inside a systemd machine.slice. The hypervisor process (qemu-system-x86_64) has access to the host's wider pool of resources, managed loosely unless strict cgroup limits are manually added.
$ systemd-cgls
Control group /:
-.slice
├─1173 bpfilter_umh
├─system.slice

└─machine.slice
  └─machine-qemu\x2d1\x2dharv41.scope
    └─8632 /usr/bin/qemu-system-x86_64 -name guest=harv41,debug-threads=on -S -…
In Harvester, every VM is encapsulated inside a Kubernetes Pod. This introduces a strict cgroup boundary (kubepods.slice).
As shown below, multiple helper processes must live alongside the primary qemu-system-x86_64 process within the same tightly limited container memory budget:
When you define a virtual machine, for example, a VM configured with 4 vCPUs, 2 GiB of memory, and 1 Ethernet interface, KubeVirt does not just allocate exactly 2 GiB of memory to the container.
Instead, KubeVirt calculates an additional baseline memory overhead required to operate the virtualization stack. This overhead budget covers:
CPU Simulators: Thread pools tracking guest state and handling context switches.
Memory Management: Tracking structures such as QEMU page tables mapping guest RAM.
Auxiliary Devices: Buffers for virtual network interfaces (NICs), storage queues, and video devices.
Depending on the guest OS type, specific kernel workloads, and heavy storage/network I/O spikes, the memory consumed by these helper tasks can quickly exceed KubeVirt's default calculations. Because Kubernetes enforces a strict hard ceiling on the Pod container, the entire container triggers a CONSTRAINT_MEMCG OOM kill the moment this boundary is breached.
Unlike traditional, stateless Kubernetes workloads where a container crash is quickly mitigated by a rapid pod restart, an OOM kill on a VM pod carries severe operational consequences:
Prolonged Downtime: A virtual machine is a stateful workload. It does not instantaneously serve traffic upon a container restart; it must undergo a full operating system boot cycle, run init scripts, and re-initialize services, drastically extending your Recovery Time Objective (RTO).
Risk of Data Corruption: Sudden terminations during flight can abruptly cut off active storage queues. If the guest OS or database engine is in the middle of a critical write operation when the host terminates the qemu process, it can result in uncommitted journals, filesystem degradation, or severe data corruption on your persistent volumes.
To address this, Harvester introduced dual-layer configurations that give administrators full flexibility over how overhead buffers are calculated.
Global Adjustment: additional-guest-memory-overhead-ratio
This cluster-wide setting functions as a multiplier for KubeVirt's automatically calculated memory overhead. For deep structural details, refer to the Harvester Advanced Documentation.
Definition: Scales the calculated overhead buffer to accommodate heavy I/O or virtualization tasks.
Default Value:1.5 (Provides a 50% safety cushion above baseline calculations).
Valid Range:0 or 1.0 to 10.0.
💡 Important Operational Notes:
Lifecycle Impact: Changes to this setting only apply to newly created virtual machines or existing VMs after they undergo a migration or a full power cycle.
System Overhead: A higher ratio increases the host container's memory allocation, guaranteeing safety for heavy workloads but scaling up the overall system resource reservation footprint.
Resource Allocation Trade-off: Setting this ratio excessively high can lock up unneeded host memory blocks, leading to predictable underutilization and significant memory waste across your compute nodes.
For specific virtual machines running intensive or non-standard workloads, a global multiplier might not offer the precision required. Harvester allows administrators to define a dedicated Reserved Memory value directly on individual VMs. For complete configuration steps, see the Harvester VM Management Documentation.
⚠️ Under the Hood Memory Carving:
When you configure this setting, Harvester explicitly scales down the available memory presented to the Guest OS inside the VM. For example, if a VM is configured with 2 GiB of memory and you set a Reserved Memory value of 256 MiB, the Guest OS will only see and utilize 1.75 GiB (2 GiB - 256 MiB).
Guaranteed Overhead Headroom: By restricting the Guest OS from consuming the top slice of its configured allocation, you guarantee an isolated, un-evictable memory runway for host helper tasks.
Targeted Safety for Heavy Workloads: This mechanism is highly practical for mission-critical, high-performance, or special-purpose workloads (such as nested virtualization layers or intensive database engines). It effectively prevents the VM from running into host-level cgroup OOM termination by proactively limiting its internal usage boundaries, removing the risk of unexpected node-level kills.
Optimized Cluster Usability: Using per-VM reservations eliminates the major disadvantage of cranking up the global additional-guest-memory-overhead-ratio for the whole cluster. Instead of forcing a massive, wasteful memory overhead reservation across every idle or lightweight VM on your hosts, you can maintain a lean global default and surgically protect only the heavy workloads—striking an ideal balance between system density and ironclad stability.
By leveraging this dual-layer tunable memory architecture, Harvester fundamentally alters how host-level overhead is calculated, moving from rigid, generalized defaults to a precise, tiered enforcement model:
Total Memory Overhead = Auto-calculated Overhead * Ratio + Reserved Memory
The following matrix showcases how combinations of Reserved Memory and the Overhead Ratio change the actual layout of the Guest OS space versus what Kubernetes reserves as a hard boundary.
VM Configured Memory
Reserved Memory
additional-guest-memory-overhead-ratio
Guest OS Memory
POD Container Memory Limit
Total Memory Overhead
2 Gi
not configured
"0.0"
2 Gi - 100 Mi
2 Gi + 240 Mi
~340 Mi
2 Gi
256 Mi
"0.0"
2 Gi - 256 Mi
2 Gi + 240 Mi
~500 Mi
2 Gi
not configured
"1.0"
2 Gi
2 Gi + 240*1.0 Mi
~240 Mi
2 Gi
not configured
"3.0"
2 Gi
2 Gi + 240*3.0 Mi
~720 Mi
2 Gi
not configured
"1.5"
2 Gi
2 Gi + 240*1.5 Mi
~360 Mi
2 Gi
256 Mi
"1.5"
2 Gi - 256 Mi
2 Gi + 240*1.5 Mi
~620 Mi
When optimizing your Harvester cluster to eliminate host-level container OOM events, use the following operational checklist to tailor your memory strategies:
For General Workloads:
Stick to the default ratio of 1.5, or configure a slightly higher value of 2.0. This ensures that standard Guest operating systems receive exactly the memory requested while scaling out a stable, predictable background overhead buffer across the cluster.
For High I/O and Storage-Heavy VMs:
If you observe periodic KVM OOM events during massive backup windows, large-scale data syncs, or intensive disk read/write cycles, increase the individual VM's allocation or implement a targeted Reserved Memory configuration to safely expand the helper overhead pool.
For GPU Passthrough Workloads:
Virtual machines utilizing direct hardware acceleration or GPU passthrough are prime candidates for explicit Reserved Memory carving. The underlying host-side device drivers and memory-mapped I/O (MMIO) windows for high-performance graphics hardware require a significantly higher, specialized memory footprint outside the guest OS space. Allocating dedicated per-VM reserved memory prevents driver-instigated cgroup allocation breaches, keeping both the hardware pipeline and the hypervisor completely stable.
The Problem: In Harvester's Kubernetes-native architecture, every virtual machine is bound by a strict Pod container limit. While this rigid cgroup boundary is essential for security, ensuring a single rogue or leaking VM can never starve neighboring workloads or crash the bare-metal host, it means heavy storage/network I/O, device drivers, or GPU passthrough can cause internal helper processes to breach this hard ceiling, triggering a sudden host-level OOM kill.
The Solution: Harvester eliminates these crashes without losing secure resource control using a dual-layer memory tuning strategy:
Globally: The additional-guest-memory-overhead-ratio scales out a safety cushion cluster-wide for newly created or migrated VMs.
Per-VM: The Reserved Memory setting surgically carves out a chunk of the VM's configured RAM exclusively for background helper tasks—preventing wasteful memory reservations across the cluster while safely anchoring high-performance, mission-critical workloads.
Appendix: Lab Simulation — Manually Triggering the Host-Level OOM
For engineers looking to validate this behavior safely in a staging environment, you can replicate this multi-process cgroup breach. A detailed script and case study can be found in the Harvester Development Summary: OOM Investigation.
The simulation process highlights a fundamental truth about modern virtualization boundaries:
The Guest OS is Trustworthy: Testing shows that modern guest operating systems handle internal resource limits reliably. If a runaway application inside the guest OS eats up all available RAM, the guest kernel safely steps in and kills that specific process internally. The VM itself survives, and from the host's perspective, the virtual machine continues running normally.
The Host Cgroup Boundary is the Weak Link: The true host-level crash only happens if processes inside the host cgroup expand unexpectedly. If an infrastructure task or helper process inside the Pod container balloons, it consumes the memory buffer that KubeVirt set aside, causing the entire cgroup, the VM's carrier, to slam into the hard Kubernetes ceiling and trigger a host-level OOM kill.
Node selector constraints can prevent the scheduler from live-migrating a virtual machine to a target node. This often indicates a mismatch between the virtual machine's requirements and the node's capabilities.
A node selector may require a specific CPU feature, but the target node lacks the corresponding label (for example, cpu-feature.node.kubevirt.io/fpu: "true"). This mismatch can occur when the host-model CPU models and features computed by KubeVirt change over time.
You can resolve this issue using four different approaches.
Reboot the virtual machine.
KubeVirt automatically adds node selectors (during a previous migration or initial start) that can restrict scheduling. You can clear these node selectors by rebooting the virtual machine.
Reboot the virtual machine and set up a common CPU model.
You can override KubeVirt's default host-model CPU configuration by setting up a common CPU model for virtual machine migration. The model is applied to the virtual machine as its domain CPU, and to the pod as its node selector configuration.
This is the recommended approach for environments that can tolerate restarting of virtual machines.
Modify the node labels.
If rebooting the virtual machine is not an option, you can manually manipulate the target node's labels to satisfy the scheduling requirements.
Add the node-labeller.kubevirt.io/skip-node="true" annotation to the target node.
This annotation, which persists even after upgrades, prevents KubeVirt's node-labeller from automatically adding or removing CPU-related labels on this node.
The annotation itself does not affect the pod's node selector. It only controls the presence of specific CPU-related labels on the node, which the node selector checks against. For more information, see the References section.
Identify labels that are missing from the virtual machine's node selector and add them to the target node.
You can add the missing labels using the following command:
kubectl label node<node-name><key>=<value>
This circumvents the standard scheduling restrictions, allowing the virtual machine to migrate to the target node.
If a new node that lacks the required features is added to the cluster, you must repeat these steps to allow the virtual machine to live-migrate to that node.
Remove the node labels.
If you want to ensure that the virtual machine does not acquire specific node selector constraints after live migration, you can remove the relevant CPU labels from the target node.
Add the node-labeller.kubevirt.io/skip-node="true" annotation to the target node.
This annotation, which persists even after upgrades, prevents KubeVirt's node-labeller from automatically adding or removing CPU-related labels on this node.
This method works only if the virtual machine's pod does not have an existing node selector that contains the labels listed in the References section. Otherwise, you must reboot the virtual machine to clear the constraints.
Check if the pod has a node selector.
kubectl get pod <pod-name> -o yaml |grep nodeSelector -A 5 -B 5
If no node selector exists, remove the relevant CPU labels from the node.
Performing this action prevents the pod from acquiring new node selector constraints, thus enabling its future migration to other nodes. However, the successful outcome of that migration is not guaranteed.
For Harvester to successfully migrate a virtual machine from one node to another, the source and target nodes must have compatible CPU models and features.
Harvester uses KubeVirt / QEMU / libvirt to manage and run virtual machines. When a VM starts, libvirt exposes a specific CPU feature set to the guest operating system. Live migration requires this CPU feature set to be identical on both source and target nodes.
Different CPU generations support different instruction sets and feature flags. If those differ, the live migration will be blocked to avoid instability or incorrect execution on the target node.
If the CPU model of a virtual machine isn't specified, KubeVirt assigns it the default host-model configuration so that the virtual machine has the CPU model closest to the one used on the host node.
KubeVirt automatically adjusts the node selectors of the associated virt-launcher Pod based on this configuration. If the CPU models and features of the source and target nodes do not match, the live migration may fail.
Let's examine an example.
When a virtual machine is first migrated to another node with the SierraForest CPU model, the following key-value pairs are added to the spec.nodeSelector field in the Pod spec.
The above nodeSelector configuration is retained for subsequent migrations, which may fail if the new target node doesn't have the corresponding features or model.
For example, compare the CPU model and feature labels added by KubeVirt to the following two nodes:
# Node A labels: cpu-model-migration.node.kubevirt.io/SierraForest:"true" cpu-feature.node.kubevirt.io/fpu:"true" cpu-feature.node.kubevirt.io/vme:"true" # Node B labels: cpu-model-migration.node.kubevirt.io/SierraForest:"true" cpu-feature.node.kubevirt.io/vme:"true"
This virtual machine will fail to migrate to Node B due to the missing fpu feature. However, if the virtual machine doesn't actually require this feature, this can be frustrating. Therefore, setting up a common CPU model can resolve this issue.
You can define a custom CPU model to ensure that the spec.nodeSelector configuration in the Pod spec is assigned a CPU model that is compatible and common to all nodes in the cluster.
Consider this example.
We have the following node information:
# Node A labels: cpu-model.node.kubevirt.io/IvyBridge:"true" cpu-feature.node.kubevirt.io/fpu:"true" cpu-feature.node.kubevirt.io/vme:"true" # Node B labels: cpu-model.node.kubevirt.io/IvyBridge:"true" cpu-feature.node.kubevirt.io/vme:"true"
If we set up IvyBridge as our CPU model in the virtual machine spec, KubeVirt only adds cpu-model.node.kubevirt.io/IvyBridge under spec.nodeSelector in the Pod spec.
Harvester allows the CPU model to be defined in the VM specification.
If host-passthrough is used, the VM exposes the exact host CPU to the guest. This provides maximum performance but completely prevents migration across different CPU generations.
If host-model is used, the VM derives a CPU model based on the host’s capabilities. This works only when all nodes expose identical CPU features. In mixed clusters, this setting commonly causes migration failures.
If an explicit CPU model is defined, the VM exposes a named CPU architecture defined by QEMU. This is the recommended approach for clusters that may contain different CPU generations.
For mixed environments, an explicit CPU model should always be used.
When selecting a CPU model, the goal is to choose the highest common denominator. This means the most modern CPU architecture that every node in the cluster supports. Pick a model supported by all nodes in your cluster, including the oldest CPU generation. Use a server-grade model that provides a reasonable set of capabilities (e.g., vector instructions, security features) without tying VMs to host-specific features. Use the same model on all VMs that need live migration.
Below are practical examples for common enterprise hardware combinations.
For a cluster that mixes Cascade Lake and Sapphire Rapids, the recommended CPU model is Cascadelake-Server. Sapphire Rapids processors are backward compatible with Cascade Lake instructions, making Cascadelake-Server the highest common denominator between these two generations.
For a cluster that mixes Skylake and Cascade Lake nodes, the appropriate model is Skylake-Server. This is the common ground between both generations. Cascade Lake includes additional AVX-512 optimizations, but using Skylake ensures compatibility across the entire cluster.
If your cluster contains Broadwell nodes along with anything newer, the safest baseline is Broadwell. Broadwell serves as a stable and widely supported baseline for older enterprise hardware. Any newer CPUs will support it.
Some CPU models (such as Cascadelake-Server) may stop working after an upgrade because of the mitigation for CVE-2019-11135. For details and the resolution, see CVE-2019-11135: TSX Asynchronous Abort.
If your virtual machines run only on a specific CPU model, you can set up a cluster-wide CPU model in the kubevirt resource.
You can edit it with kubectl edit kubevirt kubevirt -n harvester-system, then add the CPU model you want in the following spec:
spec:
  configuration:
    cpuModel: IvyBridge
Then, when a new virtual machine starts or an existing virtual machine restarts, the cluster-wide setting will be applied. The system follows these priorities when using CPU models if you configure them in both locations:
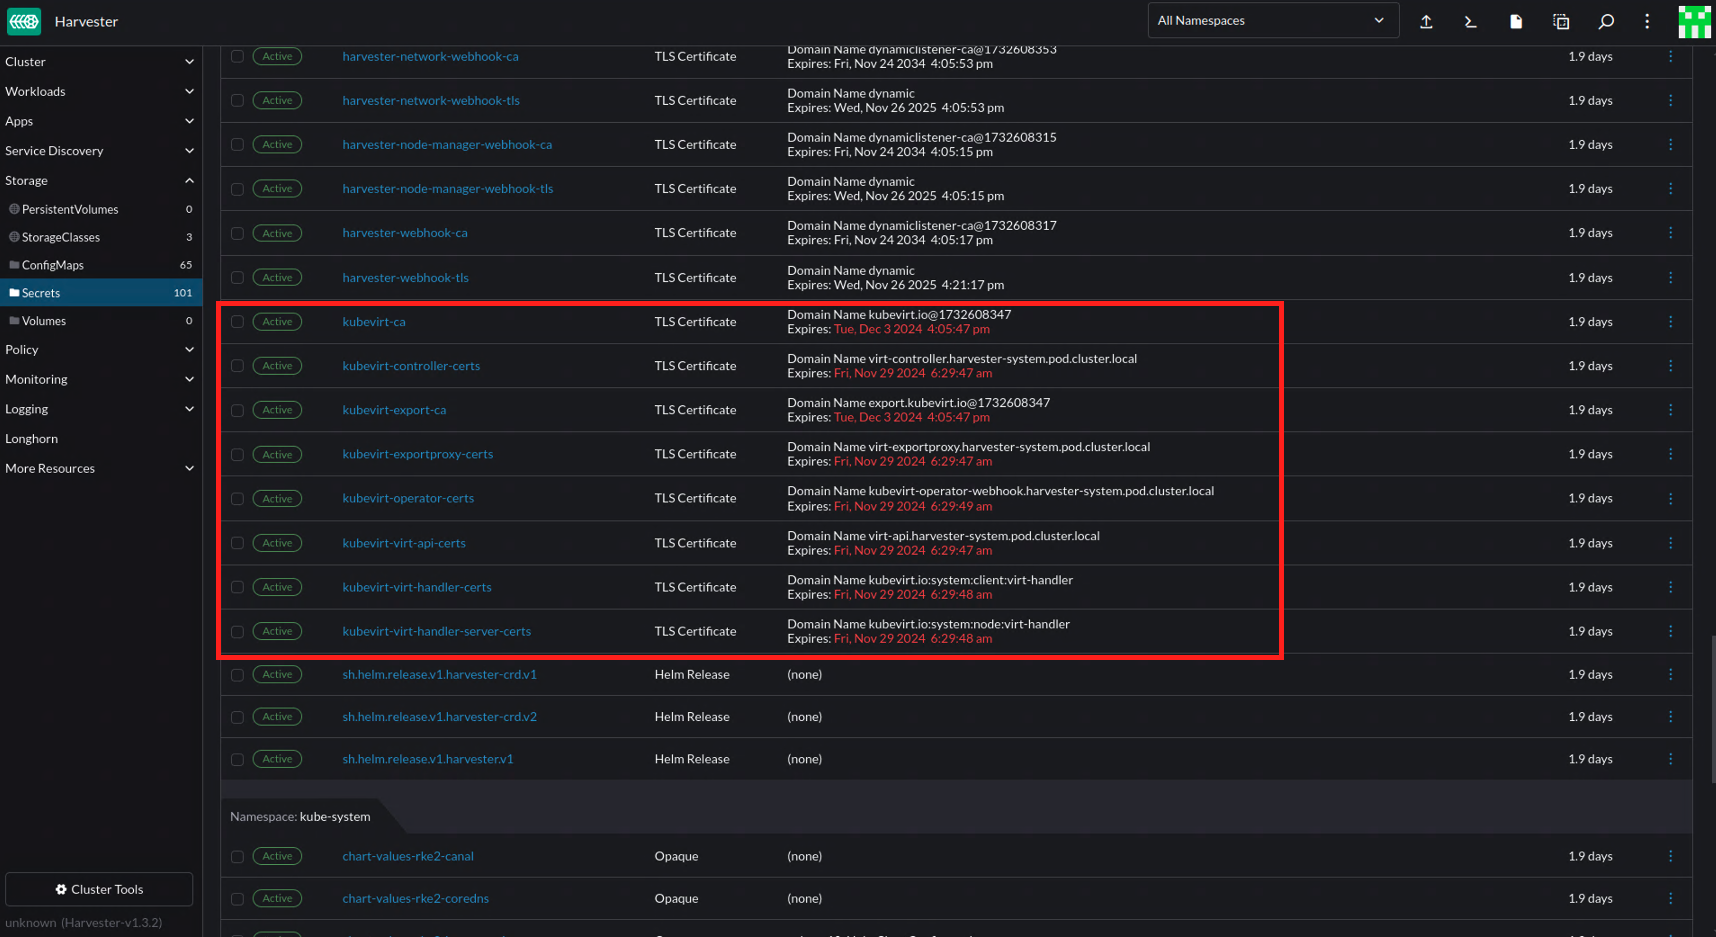
Harvester's embedded Rancher UI may display warnings about expiring KubeVirt certificates. You can safely ignore these warnings because automatic certificate rotation is handled by KubeVirt and is enabled by default.
KubeVirt provides a self-signed certificate mechanism that rotates both CA and certifcates on a defined recurring interval. You can check the setting certificateRotateStrategy by running the following command:
kubectl get kubevirt -n harvester-system -o yaml
By default, the value of certificateRotateStrategy is empty, which means that KubeVirt uses its default rotation settings and no manual configuration is required.
You can use the following fields to configure certificateRotateStrategy.
.ca.duration: Validity period of the CA certificate. The default value is "168h".
.ca.renewBefore: Amount of time before a CA certificate expires during which a new certificate is issued. The default value is "33.6h".
.server.duration: Validity period of server component certificates (for example, virt-api, virt-handler, and virt-operator). The default value is "24h".
.server.renewBefore: Amount of time before a server certificate expires during which a new certificate is issued. The default value is "4.8h".
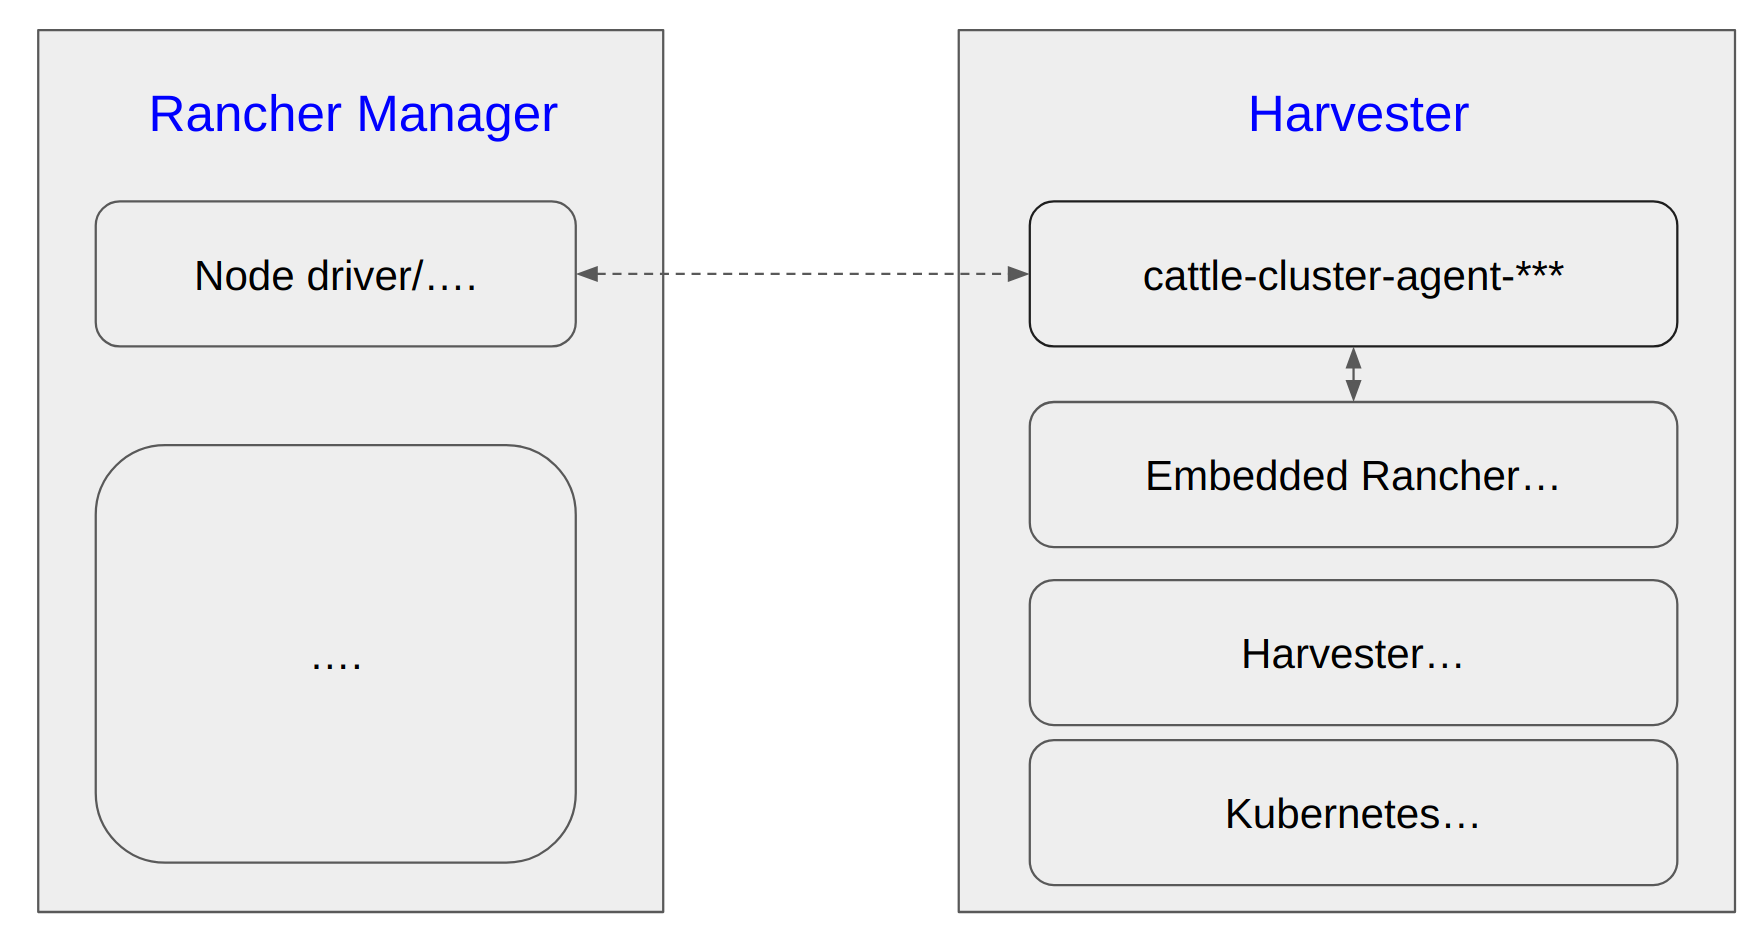
The Rancher Manager/Server is deployed independently. (Hereafter it is mentioned as Rancher Manager)
The Harvester cluster is imported to this Rancher Manager and works as a node driver.
The Rancher Manager deploys a couple of downstream K8s clusters, the machines/nodes of those clusters are backed by Harvester VMs.
There are also some traditional VMs deployed on the Harvester cluster, which have no direct connection with the Rancher Manager.
You plan to move those Harvester nodes geographically, or to power off the whole cluster for some time, it is essential to shutdown the Harvester cluster and restart later.
note
2 3 4 are optional if your Harvester cluster is mainly running as an IaaS component. This instruction covers all the above scenarios.
To safely shutdown a Harvester cluster, you need to follow the roughly reverse order of the cluster installation and the workload deployments.
Those facts need to be taken into account particularly:
The common methodology of Kubernetes operator/controller is to try things continuously until they meet expectations. When the cluster is shutting down node by node, if you don't stop those workloads in advance, they will try hard until the last node is off. It causes the last few nodes to have heavy CPU/memory/network/storage usage and increases the chance of data corruption.
Each Harvester node has limited capacity of CPU/memory/network/storage and the max-pod-number, when all workloads are crowded on the last few nodes, the unexpected pod eviction, scheduling failure and other phenomena may happen.
Harvester has embedded Longhorn as the default CSI driver, each PV can have 3 or more replicas, when replicas are rescheduled to other nodes, Longhorn will copy data from source node and rebuild the replica. Undoubtedly, stop the PVs as much as possible before the cluster shutdown to avoid the data moving.
Unlike normal Kubernetes deployments which have no PVs and are more flexible & agile to deploy anywhere on the cluster, the VMs are backed by massive sized PVs, slowly to move/migrate or even pinned on certain nodes to take the advantage of PCI-passthrough/vGPU/... and are much more sensitive to data consistency.
Needless to say, it is a bad practice to brutally power off the nodes on production environments.
For trouble-shooting purpose, it is essential to follow this instruction to generate a support-bundle file before taking any actions. And make sure the workload namespaces are added.
Harvester cluster is built on top of Kubernetes, a general requirement is that the Node/Host IP and the cluster VIP should keep stable in the whole lifecycle, if IP changes the cluster may fail to recover/work.
If your VMs on Harvester are used as Rancher downstream cluster machines/nodes, and their IPs are allocated from DHCP server, also make sure those VMs will still get the same IPs after the Harvester cluster is rebooted and VMs are restarted.
A good practice is to have detailed documents about the infrastructure related settings.
The bare metal server NIC slot/port connections with the remote (ToR) Switches.
The VLAN for the management network.
(Optional) The DHCP Server, ip-pools and ip-mac bindings for the Harvester cluster if DHCP server is used. If there is no fixed IP binding, when the server restarts after some days it may get a different IP from the DHCP server.
It is always a good practice to backup things before a whole cluster shutdown.
(Optional) Backup Downstream K8s Clusters if Possible
Harvester doesn't touch the (Rancher Manager managed) downstream K8s clusters' workload, when they are not able to be migrated to other node drivers, suggests to backup those clusters.
(Optional) Stop or Migrate Downstream K8s Clusters if Possible
Harvester doesn't touch the downstream K8s clusters' workload, but suggests to stop or migrate the downstream clusters to avoid your service interruption.
When Rancher deploys a downstream cluster on node driver Harvester, it creates a couple of VMs on Harvester automatically. Directly stopping those VMs on Harvester is not a good practice when Rancher is still managing the downstream cluster. For example, Rancher may create new VMs if you stop them from Harvester.
note
This depends on the auto-replace and/or other options on Rancher Manager.
If you have got a solution to shutdown those downstream clusters, and check those VMs are Off; or there is no downstream clusters, then jump to the step disable some addons.
Unless you have already deleted all the downstream clusters which are deploy on this Harvester, DO NOTremove this imported Harvester from the Rancher Manager. Harvester will get a different driver-id when it is imported later, but those aforementioned downstream clusters are connected to driver-id.
To safely shutdown those VMs but still keep the Rancher Manager managed downstream cluster alive, please follow the steps below:
Harvester has an embedded Rancher deployment which is used to help the lifecycle management of Harvester itself, it is different from the independently deployed Rancher Manager for multi-cluster management and more.
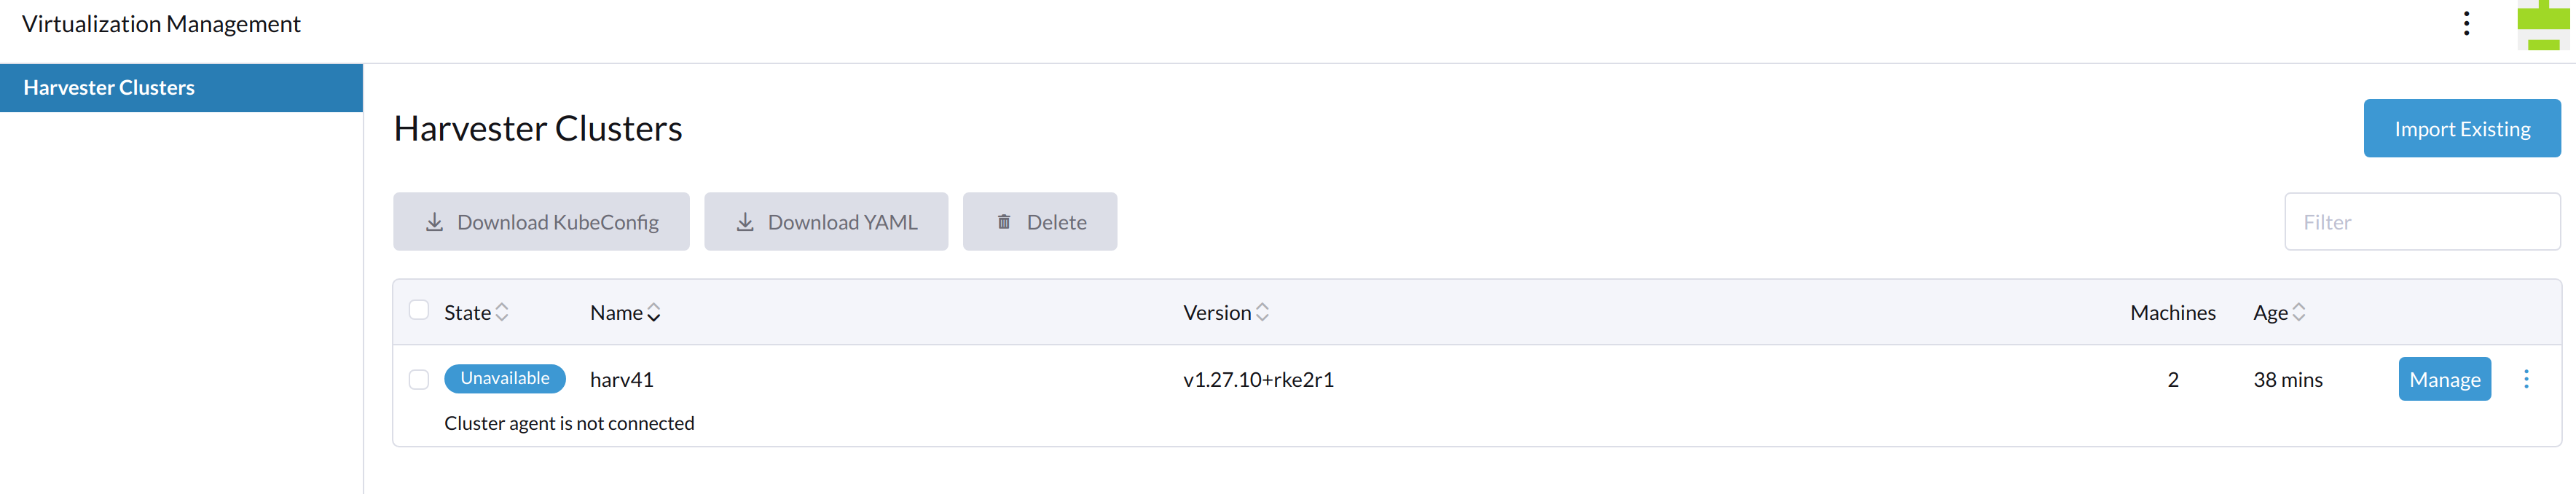
The cattle-cluster-agent-*** pod is the direct connection between Rancher Manager and Harvester cluster, and this pod is monitored and managed by the embedded Rancher in Harvester, scaling down this pod does not work. The embedded Rancher will scale it up automatically.
Run steps below to suspend the connection.
All following CLI commands are executed upon Harvester cluster.
Set the management.cattle.io/scale-available of deployment rancher to be "" instead of "3" or other values.
This change will stop the auto-scaling.
harvester$ kubectl edit deployment -n cattle-system rancher
apiVersion: apps/v1
kind: Deployment
metadata:
  annotations:
...
    management.cattle.io/scale-available: "3"  // record this value, and change it to ""
...
  generation: 16
  labels:
    app: rancher
    app.kubernetes.io/managed-by: Helm
...
  name: rancher
  namespace: cattle-system
Scale down the rancher deployment.
harvester$ kubectl scale deployment -n cattle-system rancher --replicas=0
deployment.apps/rancher scaled


harvester$ get deployment -n cattle-system rancher
NAME      READY   UP-TO-DATE   AVAILABLE   AGE
rancher   0/0     0            0           33d
Make sure the rancher-* pods are gone.
Check the rancher-* pods on cattle-system are gone, if any of them is stucking at Terminating, use kubectl delete pod -n cattle-system rancher-pod-name --force to delete it.
harvester$ kubectl get pods -n cattle-system
NAME                                         READY   STATUS        RESTARTS       AGE
..
rancher-856f674f7d-5dqb6                     0/1     Terminating   0              3d22h
rancher-856f674f7d-h4vsw                     1/1     Running       23 (68m ago)   33d
rancher-856f674f7d-m6s4r                     0/1     Pending       0              3d19h
...
Scale down the cattle-cluster-agent deployment.
harvester$ kubectl scale deployment -n cattle-system cattle-cluster-agent --replicas=0
deployment.apps/cattle-cluster-agent scaled


harvester$ kubectl get deployment -n cattle-system
NAME                        READY   UP-TO-DATE   AVAILABLE   AGE
cattle-cluster-agent        0/0     0            0           23d
Please note:
From now on, this Harvester is Unavailable on the Rancher Manager.
The Harvester WebUI returns 503 Service Temporarily Unavailable, all operations below can be done via kubectl.
Shutdown VM from the VM shell (e.g. Linux shutdown command).
Check the vmi instances, if any is still Running, stop it.
harvester$ kubectl get vmi
NAMESPACE   NAME   AGE    PHASE     IP            NODENAME   READY
default     vm1    5m6s   Running   10.52.0.214   harv41     True


harvester$ virtctl stop vm1 --namespace default
VM vm1 was scheduled to stop

harvester$ kubectl get vmi -A
NAMESPACE   NAME   AGE    PHASE     IP            NODENAME   READY
default     vm1    5m6s   Running   10.52.0.214   harv41     False


harvester$ kubectl get vmi -A
No resources found

harvester$ kubectl get vm -A
NAMESPACE   NAME   AGE   STATUS    READY
default     vm1    7d    Stopped   False
The volumes should be in state detached, check the related workload if some volumes are still in state attached.
harvester$ kubectl get volume -A
NAMESPACE         NAME                                       DATA ENGINE   STATE      ROBUSTNESS   SCHEDULED   SIZE          NODE     AGE
longhorn-system   pvc-3323944c-00d9-4b35-ae38-a00b1e8a8841   v1            detached   unknown                  5368709120             13d
longhorn-system   pvc-394713a4-d08c-4a45-bf7a-d44343f29dea   v1            attached   healthy                  6442450944    harv41   8d    // still attached and in use
longhorn-system   pvc-5cf00ae2-e85e-413e-a4f1-8bc4242d4584   v1            detached   unknown                  2147483648             13d
longhorn-system   pvc-620358ca-94b3-4bd4-b008-5c144fd815c9   v1            attached   healthy                  2147483648    harv41   8d    // still attached and in use
longhorn-system   pvc-8174f05c-919b-4a8b-b1ad-4fc110c5e2bf   v1            detached   unknown                  10737418240            13d
If your cluster has one Witness Node and the etcd leader happens to be on this node.
harvester$ kubectl get nodes -A
NAME     STATUS     ROLES                       AGE    VERSION
harv2    Ready      <none>                      25d    v1.27.10+rke2r1  // worker node
harv41   Ready      control-plane,etcd,master   55d    v1.27.10+rke2r1  // control-plane node
harv42   Ready      control-plane,etcd,master   55d    v1.27.10+rke2r1  // control-plane node
harv43   Ready      etcd                         1d    v1.27.10+rke2r1  // witness node

+------------------------------+------------------+---------+---------+-----------+------------+-----------+------------+--------------------+--------+
|           ENDPOINT           |        ID        | VERSION | DB SIZE | IS LEADER | IS LEARNER | RAFT TERM | RAFT INDEX | RAFT APPLIED INDEX | ERRORS |
+------------------------------+------------------+---------+---------+-----------+------------+-----------+------------+--------------------+--------+
| https://192.168.122.141:2379 | c70780b7862269c9 |   3.5.9 |   34 MB |     false |       true |        46 |    6538829 |            6538829 |        |
| https://192.168.122.142:2379 | db04095b49eb5352 |   3.5.9 |   34 MB |     false |       true |        46 |    6538829 |            6538829 |        |
| https://192.168.122.143:2379 | a21534d02463b347 |   3.5.9 |   34 MB |      true |      false |        46 |    6538829 |            6538829 |        |
+------------------------------+------------------+---------+---------+-----------+------------+-----------+------------+--------------------+--------+
Run kubectl delete pod -n kube-system etcd-name command to delete the etcd pod on the witness node to trigger the pod replacement and leader re-election so that the etcd leader will be located on one of the control-plane nodes. Check the etcd leader again to make sure.
If the Harvester cluster has been moved to a new location, or has been off for days, or your infrastructure has changes, check and test the network stability.
5.1 Restart the Control-plane Nodes and the Witness Node
The first step is to start those etcd located nodes one after another.
Power on the last shutdown node first. After about three minutes, continue the next step.
When you check the etcd pod log on this node, the following message may be observed.
sent MsgPreVote request to db04095b49eb5352 at term 5

"msg":"prober detected unhealthy status","round-tripper-name":"ROUND_TRIPPER_RAFT_MESSAGE","remote-peer-id":"db04095b49eb5352","rtt":"0s","error":"dial tcp 192.168.122.142:2380: connect: no route to host"
The etcd is wating for the other two members to be online and then vote a leader.
Restart the Rest of Control-plane Nodes and the Witness Node
Power on the rest nodes which also hosted the etcd pod before.
Wait until all the three control-plane nodes or possibly two control-plane and one witness nodes are Ready.
From CLI:
harvester$ kubectl get nodes -A
NAME     STATUS   ROLES                       AGE   VERSION
harv41   Ready    control-plane,etcd,master   54d   v1.27.10+rke2r1
harv42   Ready    control-plane,etcd,master   54d   v1.27.10+rke2r1
harv43   Ready    control-plane,etcd,master   54d   v1.27.10+rke2r1
The etcd forms a quorum and can tolerant the failure of one node.
note
If the embedded Rancher was not scaled down before, this step can also be:
The following EXTERNAL-IP should be the same as the VIP of the Harvester cluster.
harvester$ kubectl get service -n kube-system ingress-expose
NAME             TYPE           CLUSTER-IP     EXTERNAL-IP       PORT(S)                      AGE
ingress-expose   LoadBalancer   10.53.50.107   192.168.122.144   443:32701/TCP,80:31480/TCP   34d
Harvester deploys some basic components on the following namespaces. When a bare-metal server is powered on, it may take upto around 15 minutes for the Harvester OS to be running and all the deployments on this node to be ready.
If any of them continues to show the status like Failed/CrashLoopBackOff, a troubleshooting is needed to confirm the root cause.
If any of Longhorn PODs continues to show the status like Failed/CrashLoopBackOff, do not execute the following steps as many of them rely on the Longhorn to provision persistant volumes for running.
When the Storage Network has been enabled on the cluster, follow those steps to check if the Longhorn PODs have the correct second IP assigned to them.
After the Harvester cluster is re-connected to the Rancher Manager successfully, the Rancher Manager will handle the downstream K8s clusters' machines(vms) automatically. Wait until all the downstream clusters are ready.
Generate a new support-bundle file on the Harvester cluster.
Together with the previously generated support-bundle file, the two files record the cluster settings, configurations and status before shutting down and after rebooting. It is helpful for troubleshooting.
Harvester does not allow you to change the cluster token even if RKE2 is a core component of Harvester.
The RKE2 documentation states that the November 2023 releases of RKE2 (v1.28.3+rke2r2, v1.27.7+rke2r2, v1.26.10+rke2r2, and v1.25.15+rke2r2) allow you to rotate the cluster token using the command rke2 token rotate --token original --new-token new.
During testing, the command was run on the first node of a cluster running Harvester v1.3.0 with RKE2 v1.27.10+rke2r1.
Rotate the token on initial node.
/opt/rke2/bin $ ./rke2 token rotate --token rancher --new-token rancher1

WARNING: Recommended to keep a record of the old token. If restoring from a snapshot, you must use the token associated with that snapshot.
WARN[0000] Cluster CA certificate is not trusted by the host CA bundle, but the token does not include a CA hash. Use the full token from the server's node-token file to enable Cluster CA validation.
Token rotated, restart rke2 nodes with new token
When the first cluster node was rebooted, RKE2 service was unable to start.
RKE2 log:

...
May 29 15:45:11 harv41 rke2[3293]: time="2024-05-29T15:45:11Z" level=info msg="etcd temporary data store connection OK"
May 29 15:45:11 harv41 rke2[3293]: time="2024-05-29T15:45:11Z" level=info msg="Reconciling bootstrap data between datastore and disk"
May 29 15:45:11 harv41 rke2[3293]: time="2024-05-29T15:45:11Z" level=fatal msg="Failed to reconcile with temporary etcd: bootstrap data already found and encrypted with different token"
May 29 15:45:11 harv41 systemd[1]: rke2-server.service: Main process exited, code=exited, status=1/FAILURE
...
Do not attempt to rotate the RKE2 token on your cluster before Harvester announces official support for this feature (even if the embedded RKE2 binary has the token rotate option).
Harvester has a webhook that checks this setting to ensure it meets all conditions, e.g. the internal IPs and CIDRs are specified in the noProxy field.
note
Avoid changing the HTTP proxy from files in the host /oem path for the following reasons:
You must manually change the HTTP proxy on each node.
Contents of local files are not automatically populated to new nodes.
Without help from the webhook, some erroneous configurations may not be promptly detected (see Node IP should be in noProxy).
Harvester may change the file naming or content structure in the future.
Harvester is built on top of Kubernetes, RKE2, and Rancher. RKE2 generates a list of *.crt and *.key files that allow Kubernetes components to function. The *.crt file expires after one year by default.
$ ls /var/lib/rancher/rke2/server/tls/ -alth

...
-rw-r--r-- 1 root root  570 May 27 08:45 server-ca.nochain.crt
-rw------- 1 root root 1.7K May 27 08:45 service.current.key
-rw-r--r-- 1 root root  574 May 27 08:45 client-ca.nochain.crt
drwxr-xr-x 2 root root 4.0K May 13 20:45 kube-controller-manager
drwxr-xr-x 2 root root 4.0K May 13 20:45 kube-scheduler
drwx------ 6 root root 4.0K May 13 20:45 .
drwx------ 8 root root 4.0K May 13 20:45 ..
-rw-r--r-- 1 root root 3.9K May 13 20:40 dynamic-cert.json
drwx------ 2 root root 4.0K May 13 20:39 temporary-certs
-rw------- 1 root root 1.7K May 13 20:39 service.key
-rw-r--r-- 1 root root 1.2K May 13 20:39 client-auth-proxy.crt
-rw------- 1 root root  227 May 13 20:39 client-auth-proxy.key
-rw-r--r-- 1 root root 1.2K May 13 20:39 client-rke2-cloud-controller.crt
...
-rw-r--r-- 1 root root 1.2K May 13 20:39 client-admin.crt
-rw------- 1 root root  227 May 13 20:39 client-admin.key
...


$ openssl x509 -enddate -noout -in /var/lib/rancher/rke2/server/tls/client-admin.crt

notAfter=May 13 20:39:42 2025 GMT
When a cluster has been running for over one year, Kubernetes components may fail to start after upgrades or node rebooting. The workaround is to delete the related files and restart the pod.
Harvester v1.3.0 added the setting auto-rotate-rke2-certs, which allows you to set the Harvester cluster to automatically rotate certificates for RKE2 services. When you enable the setting and specify a certificate validity period, Harvester automatically replaces the certificate before the specified period ends.
note
Enabling this setting on your cluster is highly recommended.
A side effect of using this default value is the expiration of authentication tokens embedded in kubeconfigs that Rancher uses to provision guest Kubernetes clusters on Harvester. When such tokens expire, Rancher loses the ability to perform management operations for the corresponding Rancher-managed guest Kubernetes clusters. Issue #44912 tracks the issue described in this article.
note
The issue affects only guest Kubernetes clusters running on Harvester that use cloud credentials created after installing or upgrading to Rancher v2.8.x.
You can patch the expired Harvester cloud credentials to use a new authentication token.
Identify the expired cloud credentials and which Harvester cluster is
affected by them.
Download a new kubeconfig file for the affected Harvester cluster.
Patch the cloud credentials. The cloud credential is stored as a secret in cattle-global-data namespace, and can be replaced with the new kubeconfig file. Ensure that the environment variable KUBECONFIG_FILE contains the path to the new kubeconfig file.
#!/bin/sh CLOUD_CREDENTIAL_ID=$1# .metadata.name of the cloud credential KUBECONFIG_FILE=$2# path to the downloaded kubeconfig file kubeconfig="$(base64 -w 0"${KUBECONFIG_FILE}")" patch_file=$(mktemp) cat>${patch_file}<<EOF data: harvestercredentialConfig-kubeconfigContent: $kubeconfig EOF kubectl patch secret ${CLOUD_CREDENTIAL_ID} -n cattle-global-data --patch-file ${patch_file} --type merge rm${patch_file}
important
macOS users must use gbase64 to ensure that the -w flag is supported.
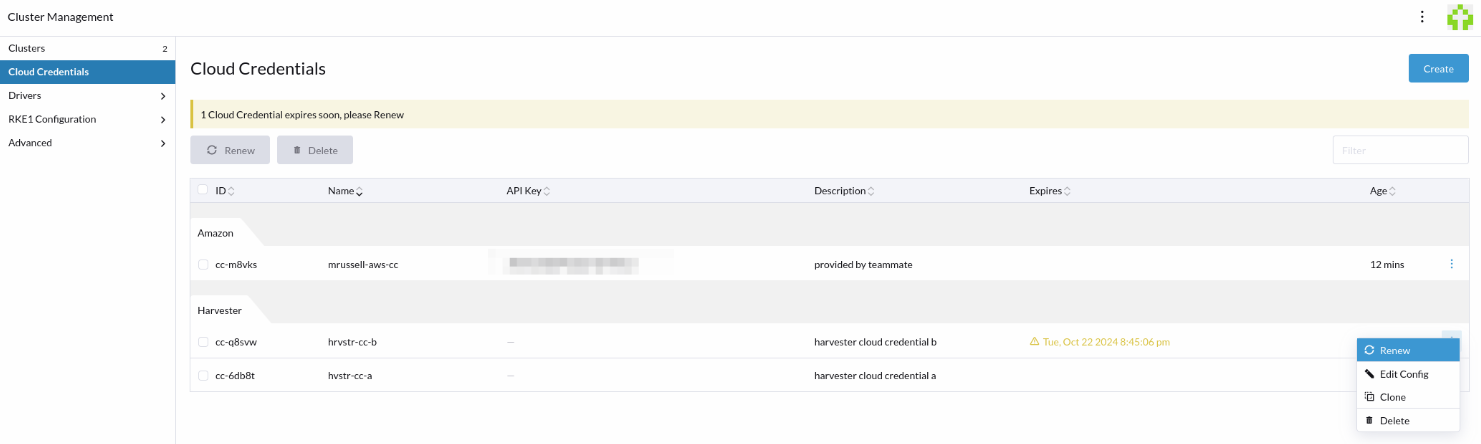
In Rancher 2.9.3 the Rancher UI displays a warning when a Harvester cloud credential or a related cluster contains an expired token. You can renew the token on the Cloud Credentials screen by selecting ⋮ > Renew, or the Clusters screen by selecting ⋮ > Renew Cloud Credential
note
When you upgrade Rancher, the Rancher UI does not display a warning for Harvester cloud credentials that expired before the upgrade was started. However, you can still renew the token on the Cloud Credentials or Clusters screen.
Expiration of kubeconfig Tokens in Rancher 2.9.4 and later versions
As previous versions, however now all expired Harvester cloud credentials will display a warning regardless of Rancher upgrade history.